Owners kept deleting the app while their plants were still alive
Owners kept telling me the same story. They log everything for two weeks, miss one day, feel guilty, and delete the app. So I rebuilt it around the two things they actually needed: a straight answer when they don't know what to do, and a missed day that costs them nothing.
This case study argues two things. That what pushes owners to quit is uncertainty rather than forgetfulness. And that a screen should not say what it does not know.
The short version
The problem. Plant apps assume people forget. What actually happens is that people get unsure, then guilty, then they're gone.
The opportunity. The gap wasn't another reminder app. Existing products compete on identification, reminders and content. YourNature competes on confidence and recovery — knowing what to do, and getting back on track after a missed day.
What I changed. Three task cards became one. Today's tasks took the slot friends' stories had. Progress became a history that only grows, so a missed day costs nothing. And the community goal was rebuilt from scratch after a usability session broke it.
What I can prove. Nothing shipped, so there is nothing to measure in an app store. What I ran instead: ten interviews with plant owners from three Facebook plant groups, two usability sessions on the prototype (one of which killed the community goal and rebuilt it), and a comparative test of the two final task cards with 12 owners, where the winner was faster on every measure.
The problem
In ten interviews, the thing people quit over was feeling like they failed.
I messaged every member I could reach across three Facebook plant groups, and ten agreed to talk. I didn't ask what features they wanted. I asked about the last time they gave up on an app.
“I log every single drop of water for two weeks. Then life gets busy and I miss a day. Then three days. Then I just give up on the app.” Plant owner, Facebook group — the sentence the whole project answers
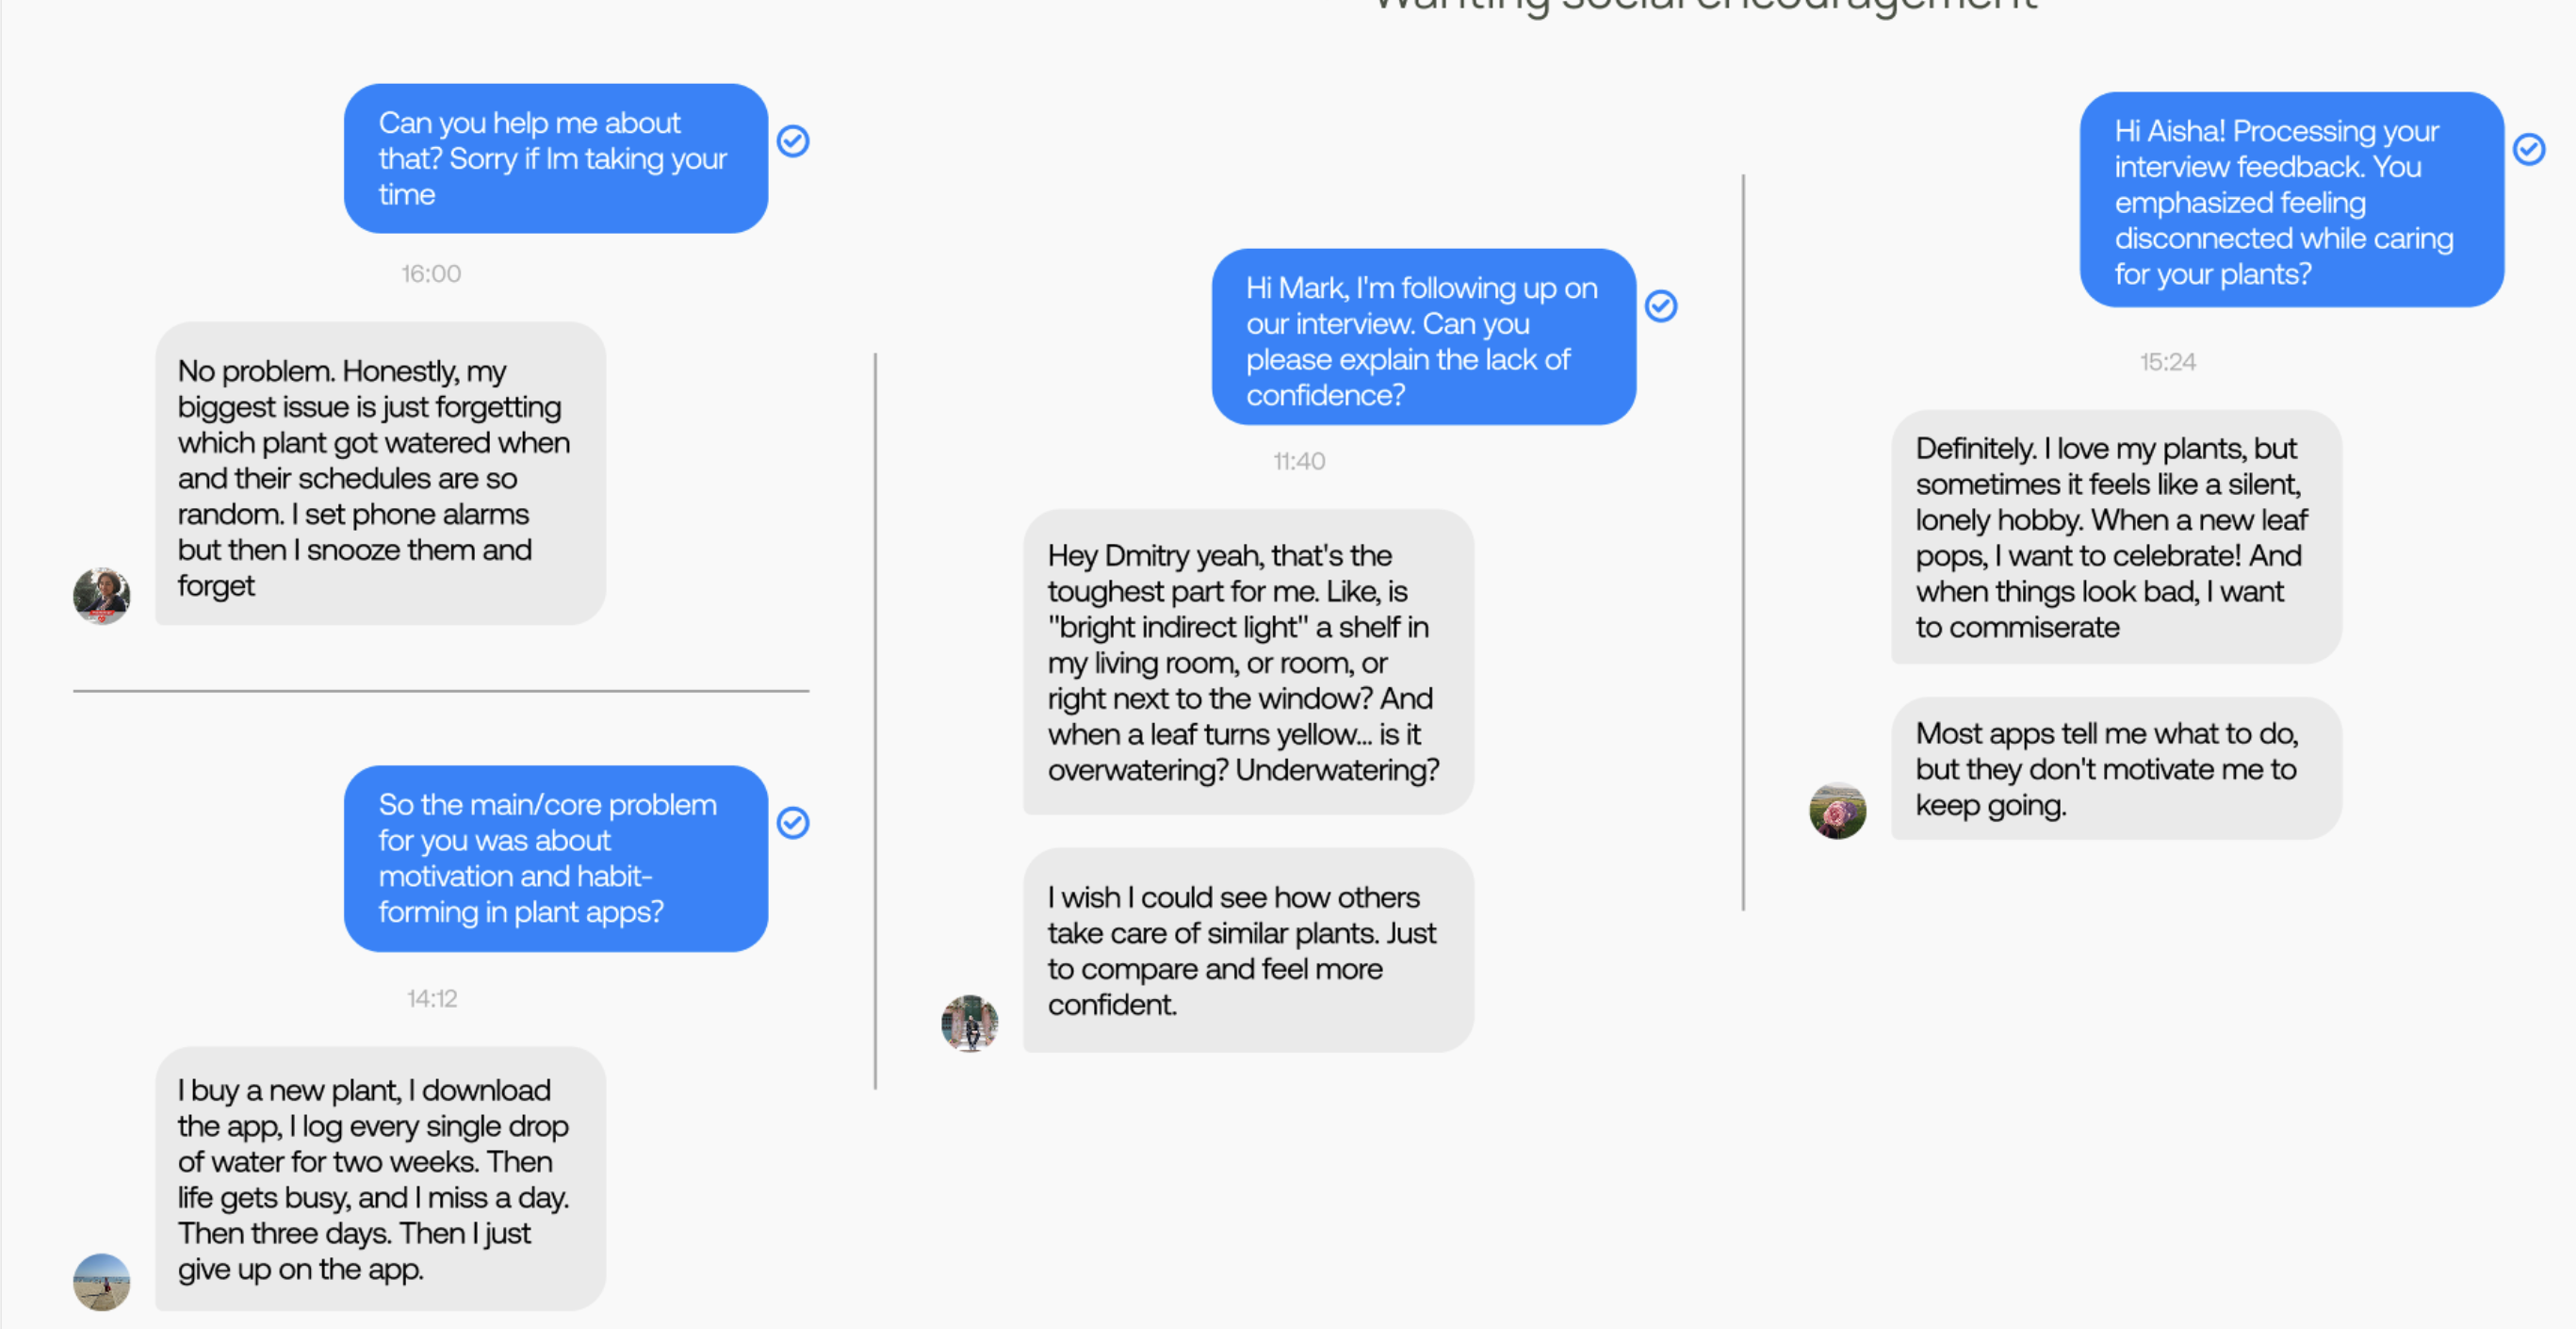
Ten conversations
Everyone in a plant group is still in the hobby, so this sample leans towards people who stayed — worth knowing before you trust it. Everyone who later used the prototype came from the same three groups, so the testing carries the same lean.
Four reasons to quit
I grouped the quotes by what people did after they got stuck. Four reasons came out: unclear amounts, late-means-failed, invisible progress, solitary hobby.
Checked against published work
Ten people can show you a pattern. How common it is takes more than ten, so nothing reached a screen until I'd checked it against a 2,000-person ownership survey, university horticulture extensions, and a CHI study on habit formation.
The brief stopped being “remind people”. It became two questions — how much, and am I doing this right — plus one rule: a missed day must never feel like failure. Everything after this follows that, or catches where I didn't.
Who I spoke to, and the sources behind it
| Plant owners interviewed | 10 |
| Beginner / experienced | 4 / 6 |
| Age range | 26 to 56 |
| Had used a plant-care app before | 7 |
| Of those ten, went on to use the prototype | 2 |
| Total people who used the prototype | 12 |
| Recruitment | 3 Facebook groups |
The research patterns are composites, synthesised from ten interviews, so no individual is represented by one of them and there are no names — everyone spoke on the understanding that they wouldn't be identifiable. The quotations are not composites. Each is a verbatim statement from one participant, chosen because it states that pattern most plainly.
- OnePoll for Article (2020). Survey of 2,000 US millennials aged 25–39 on houseplant ownership.
- University of Maryland Extension, Winter Indoor Plant Problems. Overwatering named the number one reason indoor plants die.
- Iowa State University Extension, Diagnosing Houseplant Problems Related to Poor Culture.
- Stawarz, K., Cox, A. L. & Blandford, A. (2015). Beyond Self-Tracking and Reminders. CHI '15, 2653–2662.
- Schultz, W., Dayan, P. & Montague, P. R. (1997). A Neural Substrate of Prediction and Reward. Science 275(5306).
- Sailer, M. et al. (2017), Computers in Human Behavior. Deci, Koestner & Ryan (1999). JMIR Serious Games (2021) on leaderboards.
The screens
Five screens, and the question each one answers.
None of these started as a feature idea. If a screen couldn't name the question it answered, it didn't make it in.
| Reason people quit | What it looks like | Answered by |
|---|---|---|
| Unclear amounts | People water by guess, and the app never gives them a number to hold on to. | The task card, which says how much |
| Late means failed | One red “overdue” turns a hobby into homework, and that is the sentence people quit on. | Progress that never resets when you miss a day |
| Invisible progress | Two months of care, and the plant looks the same as it did in week one. | “Grown with you”, the plant's growth history |
| A solitary hobby | Nobody to ask when something goes wrong, so people go back to the Facebook group instead. | Community — goals and meetups |
Two of these land on the same screen, which is why the reward took the most iterations — and why breaking it, in section 07, broke two things at once.
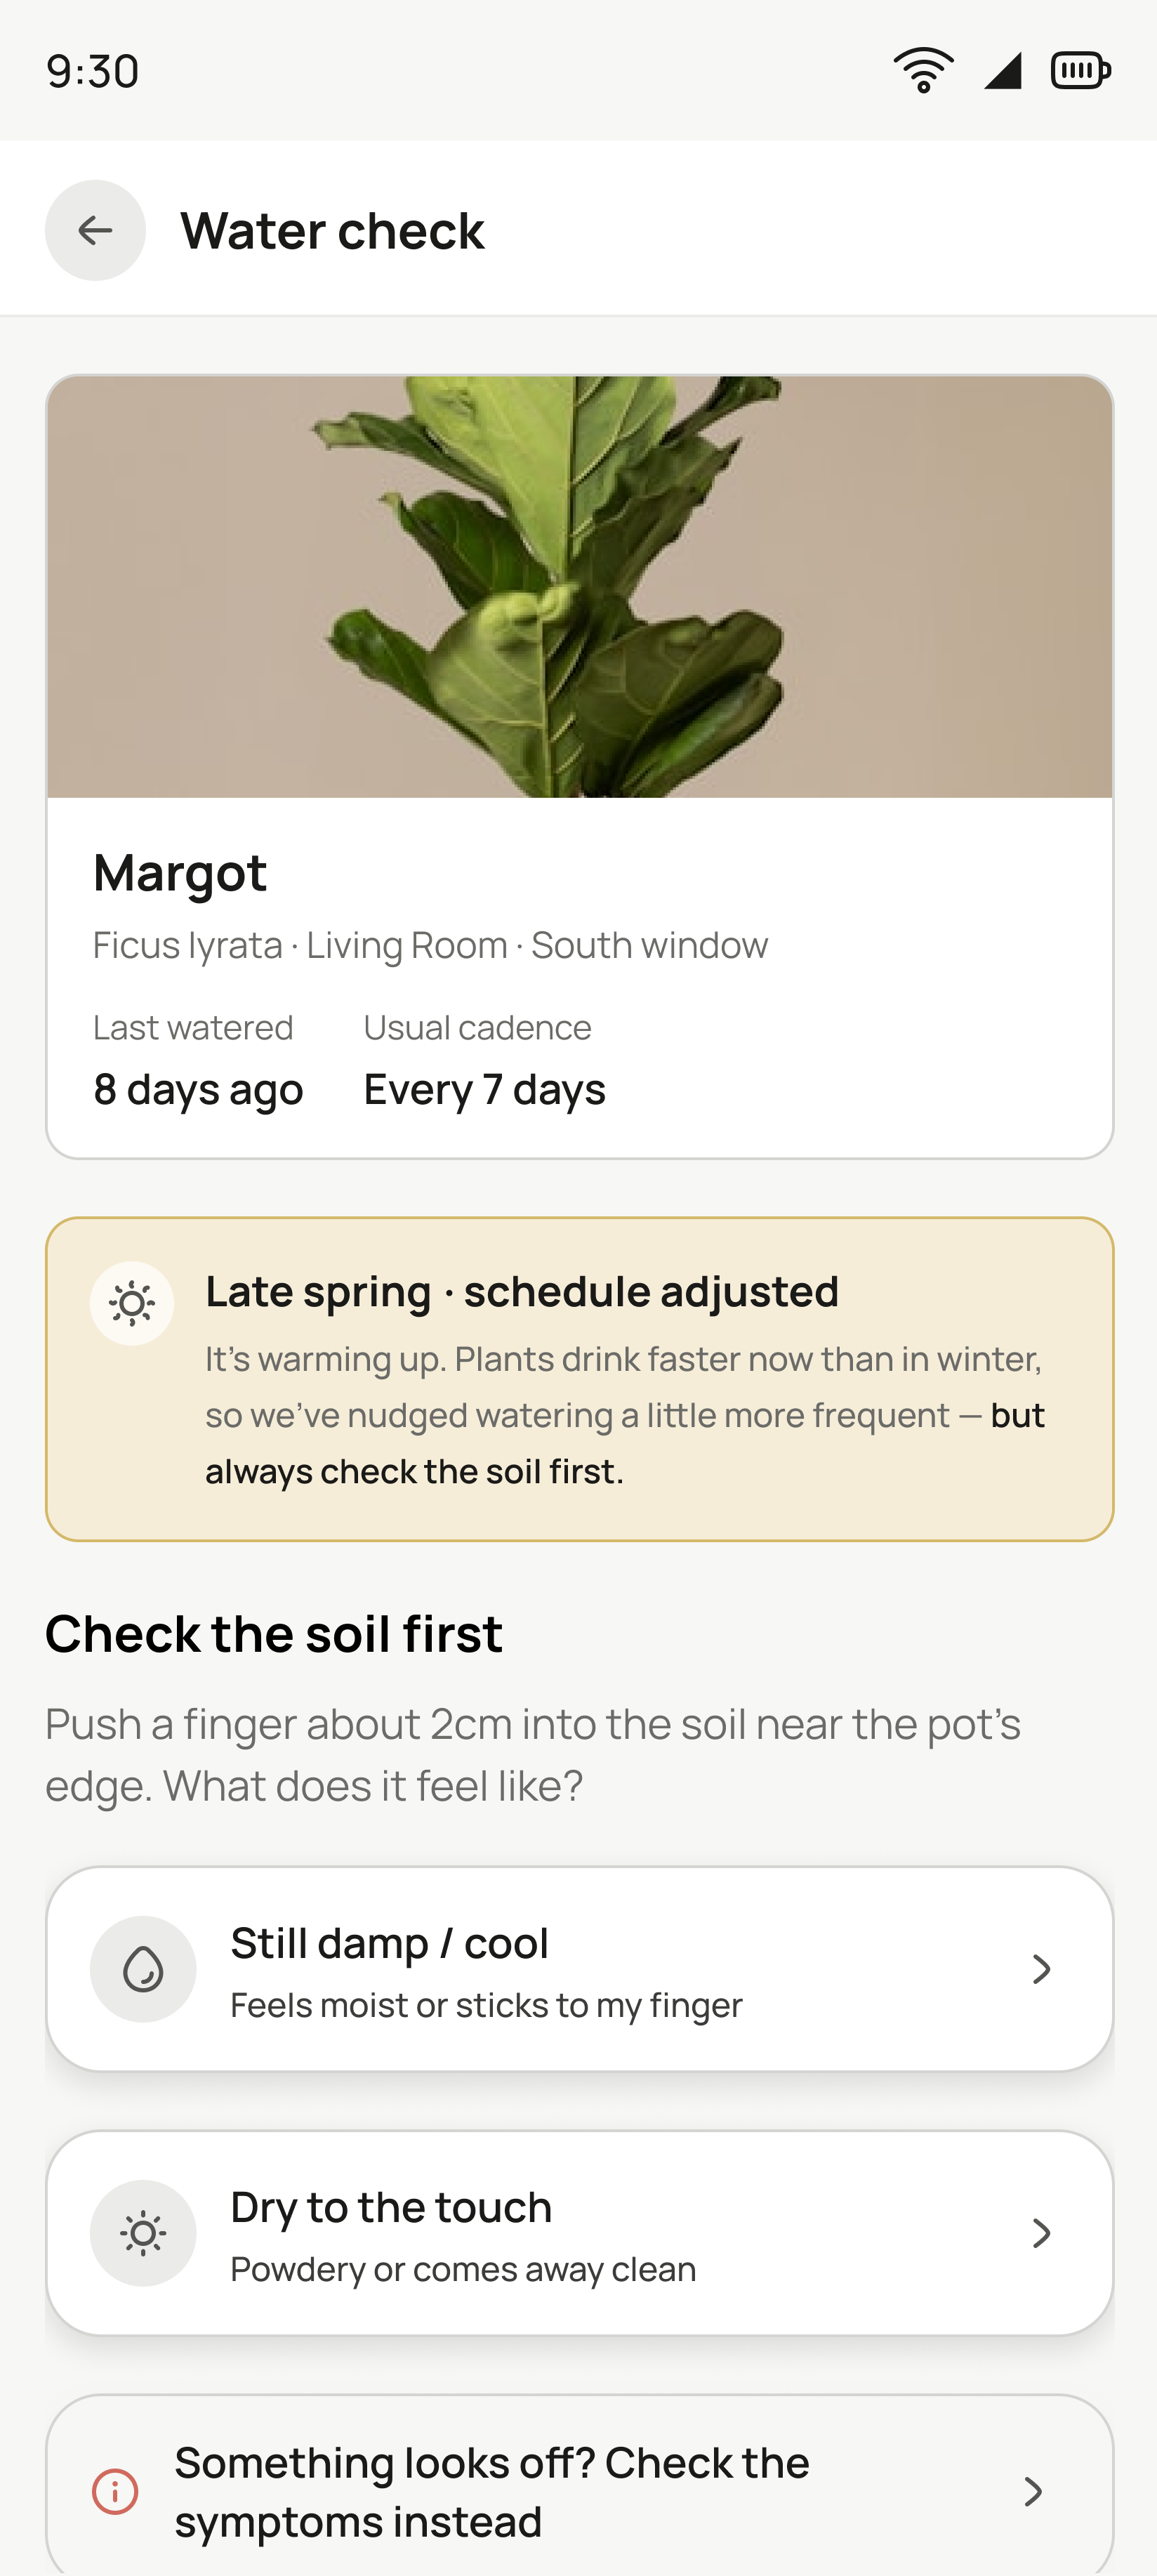
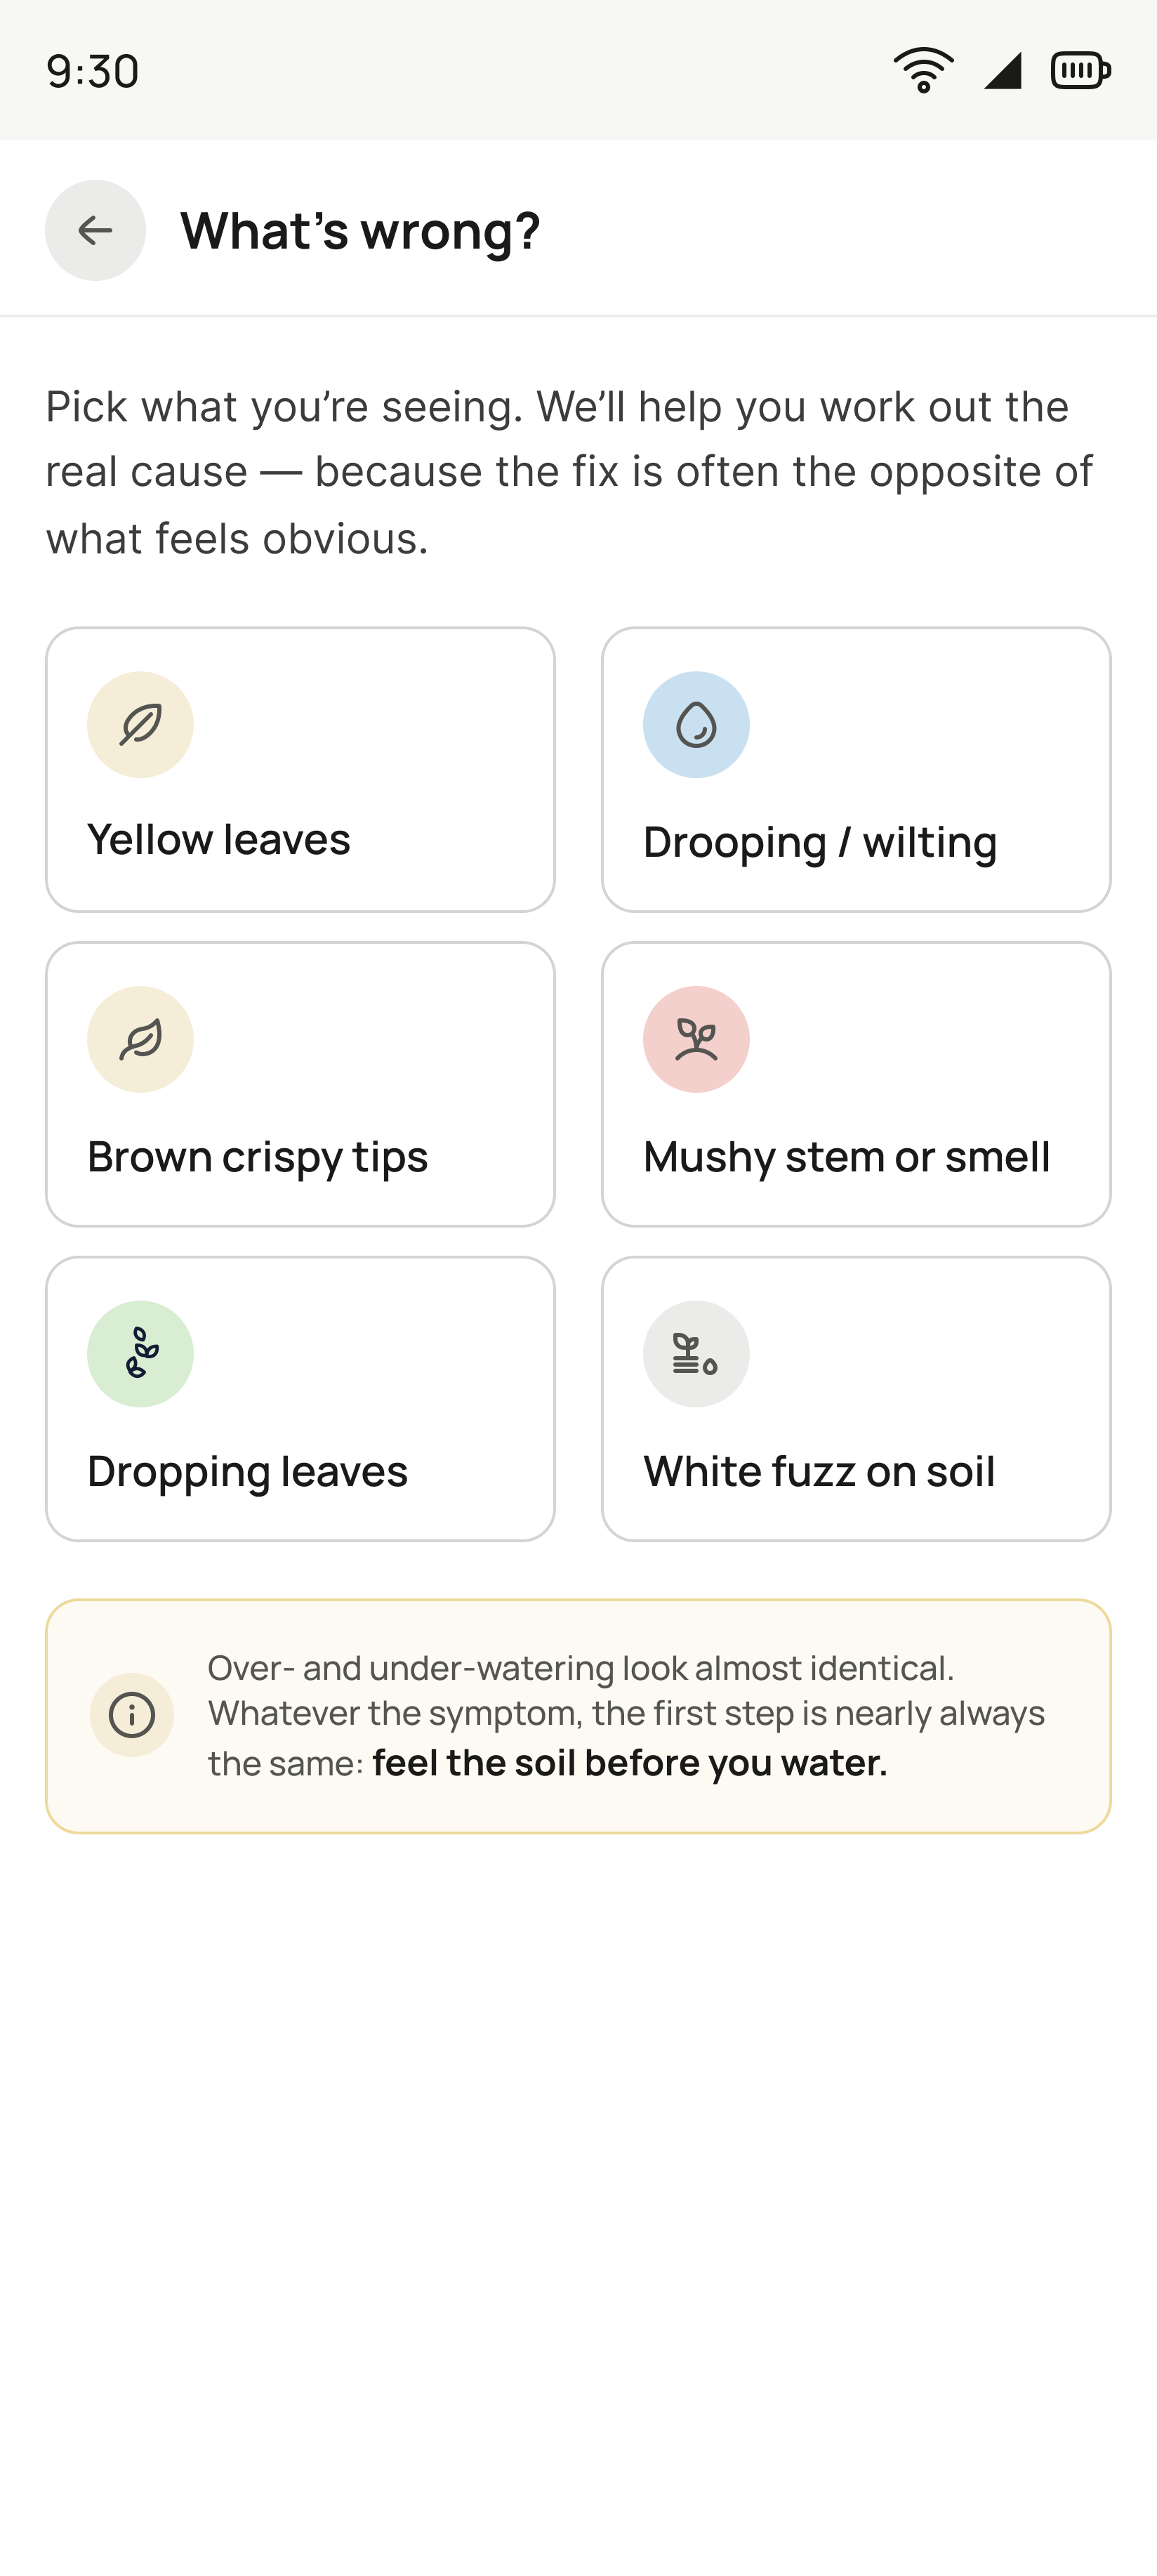
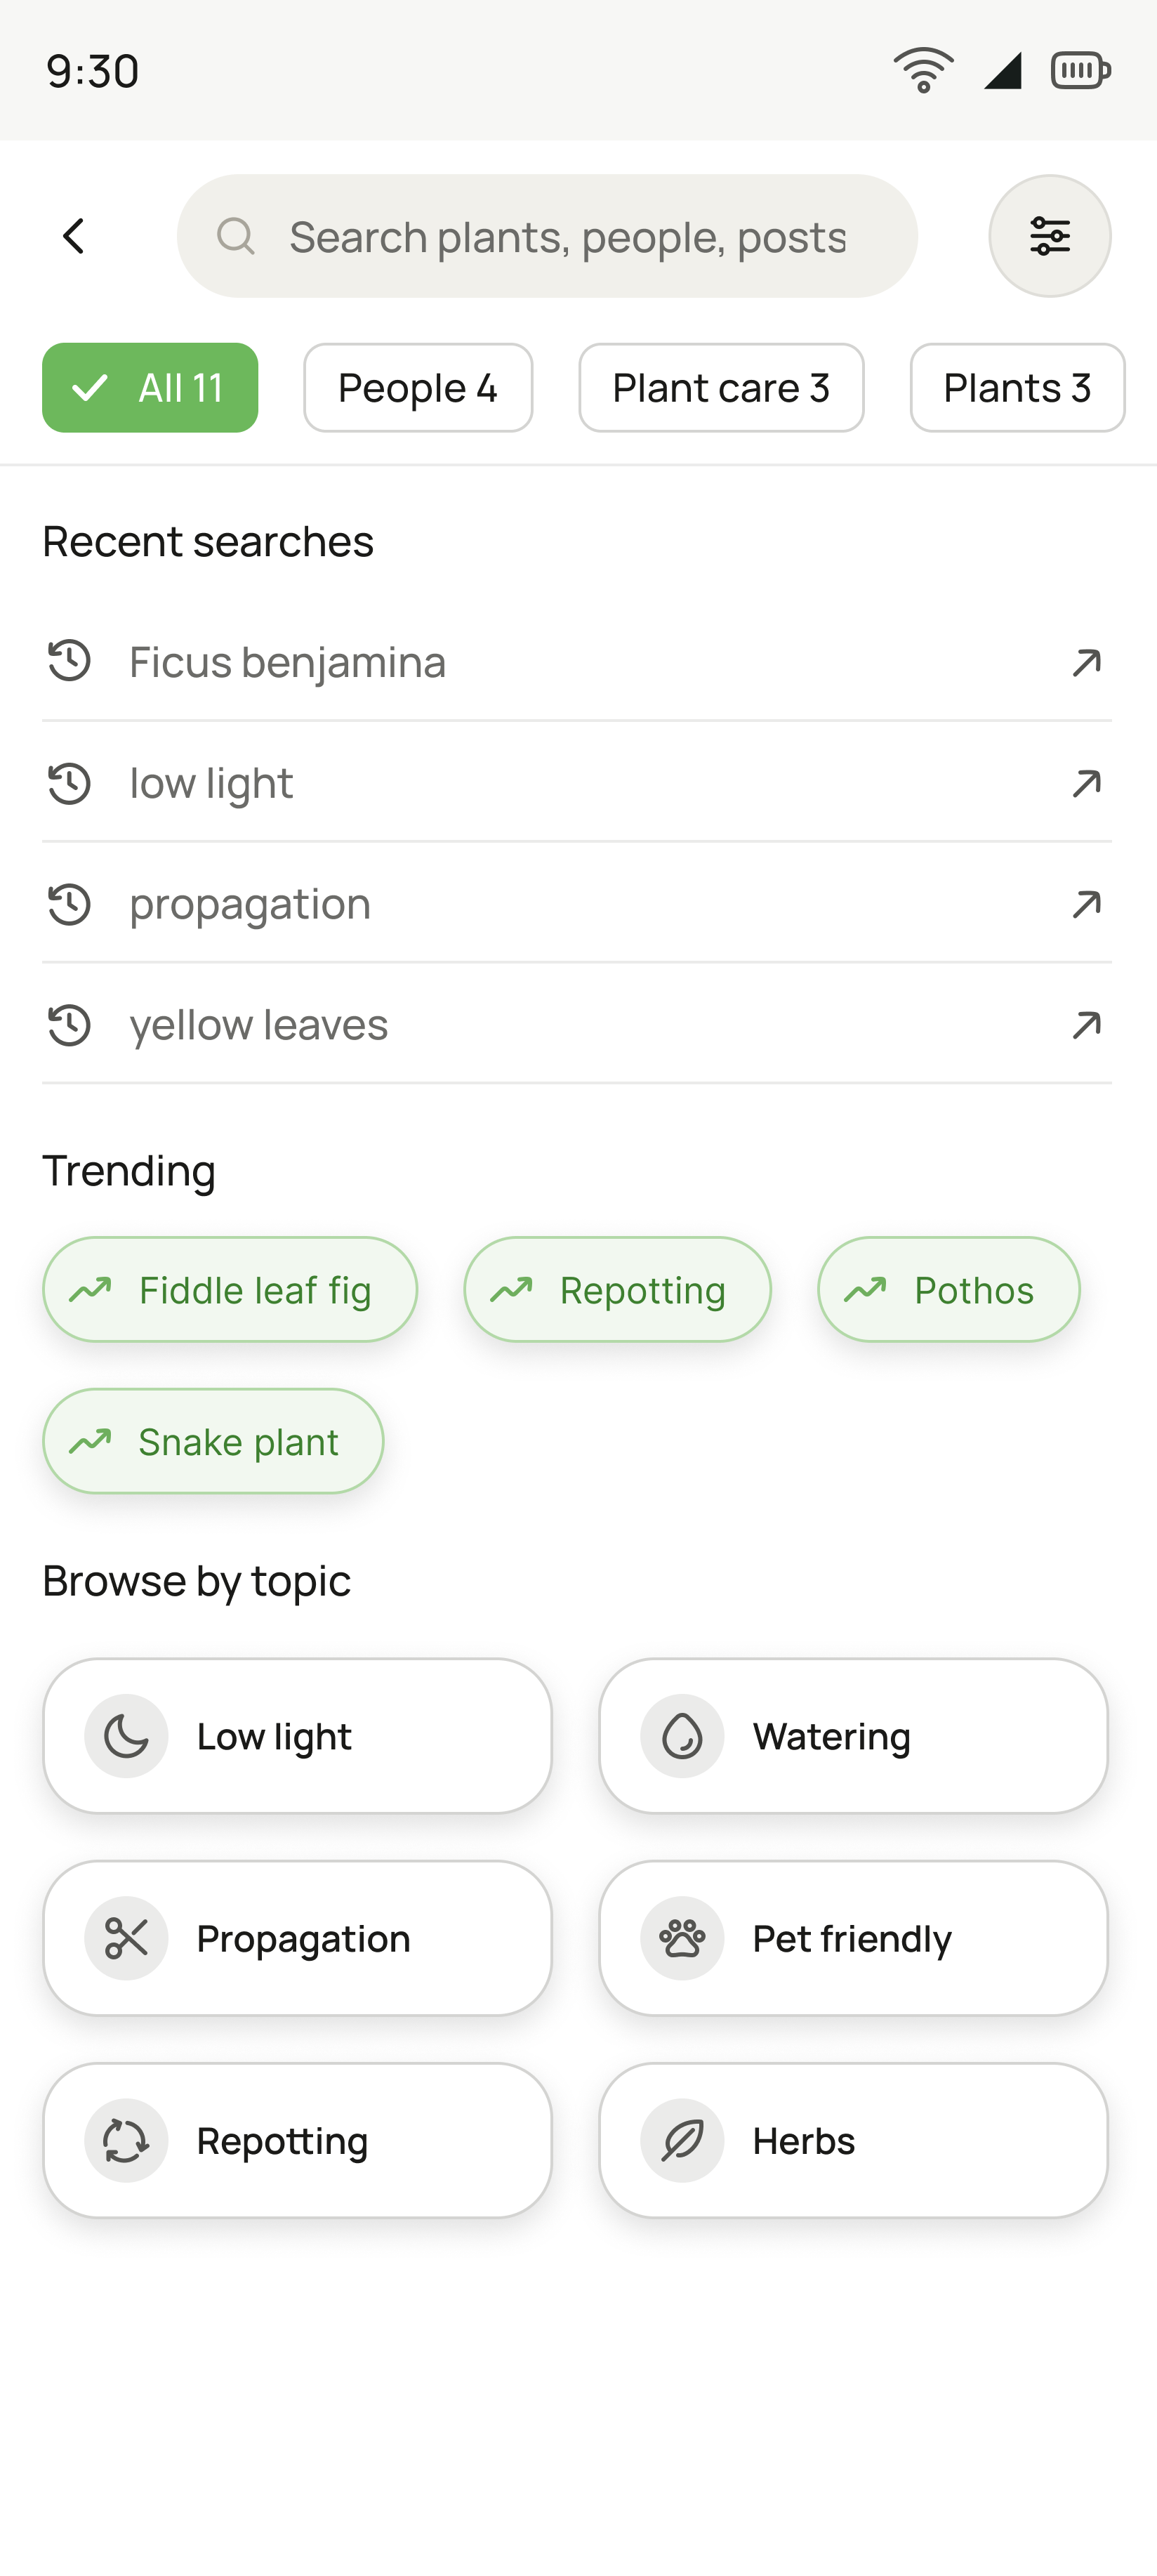
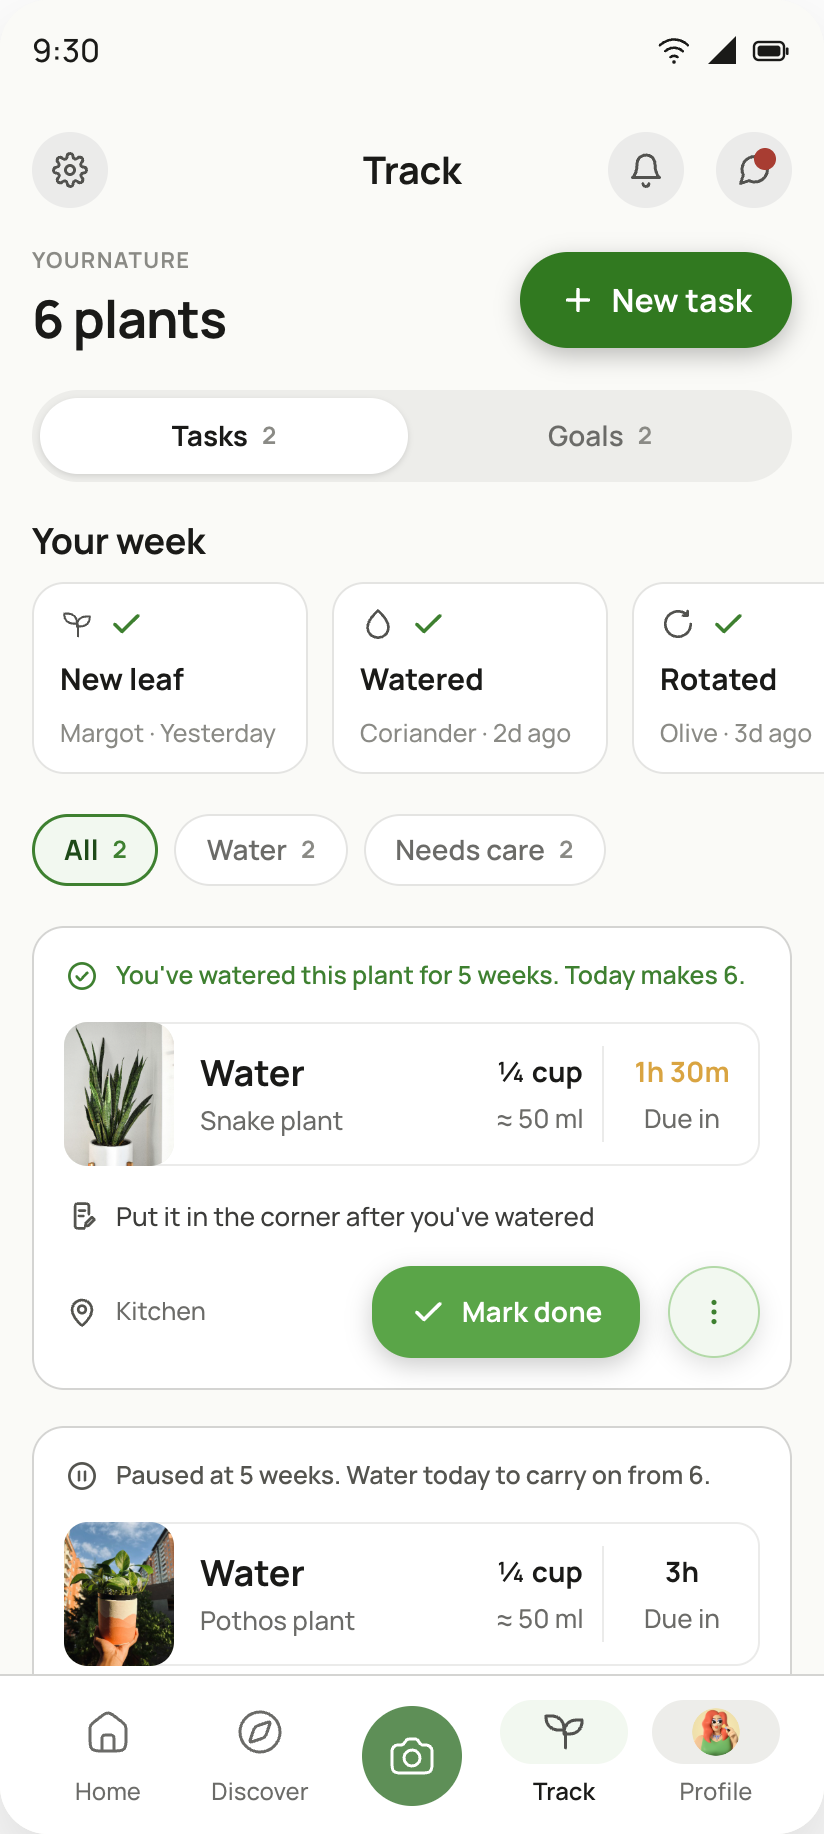
Five screens cover all four reasons people quit, and each one traces back to a sentence somebody said. Four screens I had already finished aren't here — the stories row, the sign-up wall, a badges page and a plant-of-the-week feed all went, because none of them could name their question.
One card, not three
One card ended up beating three good ones. The one component people touch every day, and the thing I iterated on hardest.
Each surface deserved its own card
Home, Track and Collection have different densities, so I drew a card for each — and each one was defensible on its own.
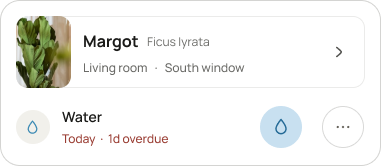
Side by side they were three different apps
None answered the question everyone had asked. The card named the plant twice and the amount never. Nothing said which control finished the task. And the loudest thing on it was “1d overdue” in red — the exact moment people told me they close the app.
One card that works everywhere
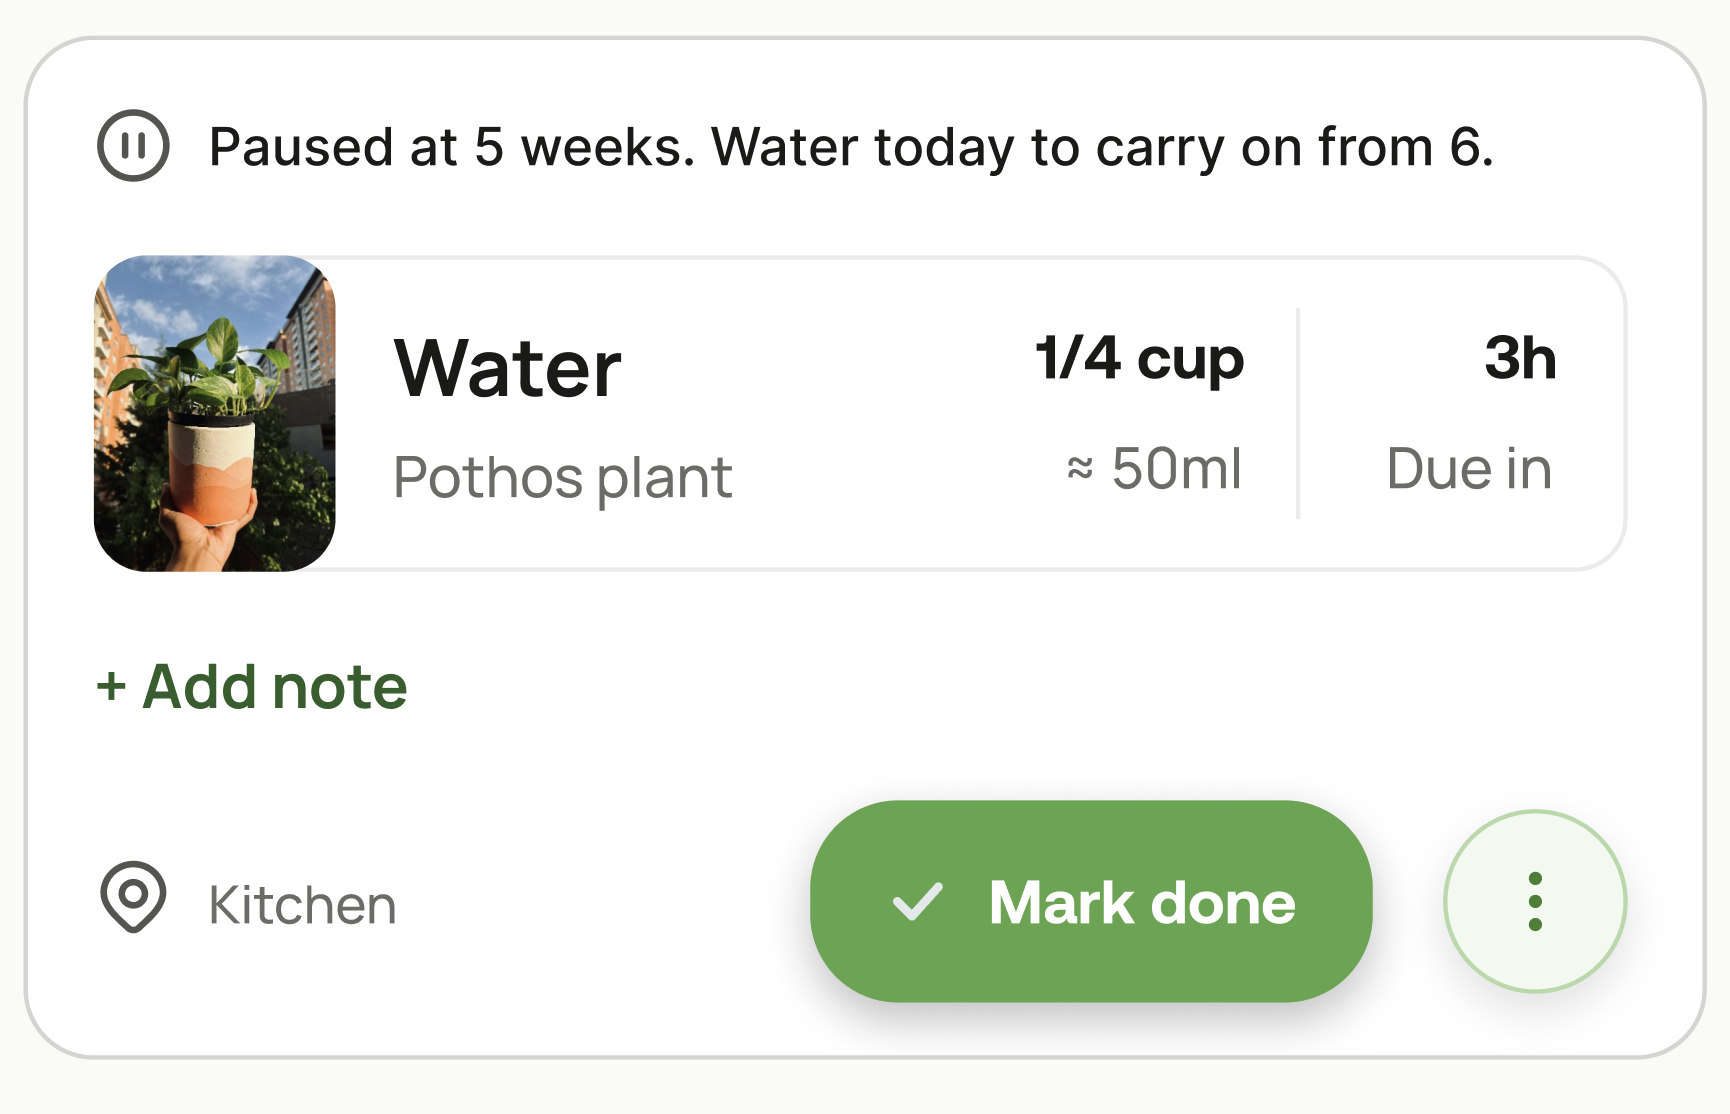
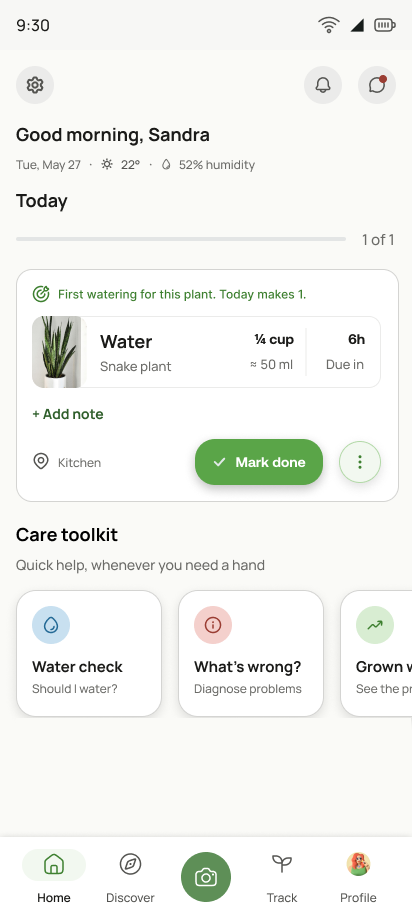
It answers four things at a glance: which plant, what task, how much, how long you've got. Mark done is the only primary action, and everything else goes behind the overflow icon in a bottom sheet.
Seven card designs over three weeks
At some point I printed the three live cards at full size and laid them side by side on a desk. When three cards are answering three different questions, you can just see it. Then I cut anything that wasn't answering one of the four questions.
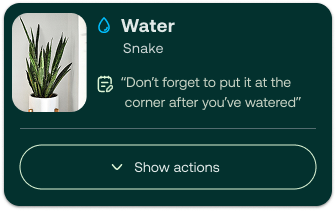
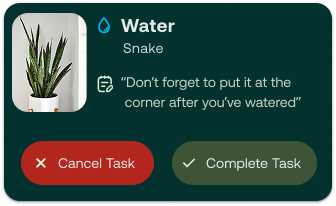
The comparative usability test
I compared my last two card versions with 12 plant owners from the same three Facebook groups. Everything in the app depends on this card and I didn't want to pick between them on taste, so I showed both cards to every person, swapped which one came first so neither had an advantage, and recorded the screen so I could time things properly afterwards.
| What I measured | Version A (design 7) | Version B (design 6) |
|---|---|---|
| Seconds to identify the primary action fastest to slowest person | 1.9 to 6.4 | 2.8 to 12.6 |
| Picked the right action with no help | 12 of 12 | 4 of 12 |
| Said how much water to give | 12 of 12 | 0 of 12 |
| Explained skip and delay correctly | 9 of 12 | 3 of 12 |
| Ease rating, 1 hard to 7 easy | 6.1 | 3.8 |
| Said they would want this card in the app | 12 of 12 | 2 of 12 |
My interpretation. I take the faster answers on Version A to mean it is easier to read, not that it takes no thought. Twelve people can tell me which of two cards is clearer. They cannot tell me it works for everyone, and I would want a bigger group before saying that. The useful part was skip and delay: nine of twelve is better than three, but it is still three people who got it wrong, and that sent me to the wording in the sheet rather than back to the card.
Where the water number comes from
Every app already reminds you. Almost none say how much, because the amount depends on the plant and where it's sitting. The conceptual model is a ballpark, on purpose:
volume = pot volume × species water factor × season × light × pot material
Soil holds roughly a fifth of the pot's volume as available water. Everything after that is a multiplier the user already knows the answer to — pot size and material asked once at setup, species class as three bands, and season and light.
The design job was making all of that cost the user nothing. Every input is something you can answer by looking at the plant, and what comes out is one number on the card. Nobody pours to the millilitre, and the number isn't asking them to — it replaces “water well”, which people read as “guess”. A rough 50 ml is a starting point you can be wrong about and correct; “water well” isn't. The coefficients would still need a horticulturist before this shipped: the design bet is on having a number at all, not on that number being exact.
The hardest small argument: “skip” cancels, “delay” keeps it owed
Delay means you still owe it, just not right now. Skip means that one's cancelled and the plant waits for its normal interval. On a weekly plant, delaying puts the next watering tomorrow, and skipping puts it six days later on its usual day.
I didn't rename anything. Under each option the sheet just says what happens, like “Keep the schedule. Next watering 5 August.” The date does the explaining, so you can see the difference while you're choosing. Changing the words was cheaper than building a new pattern.
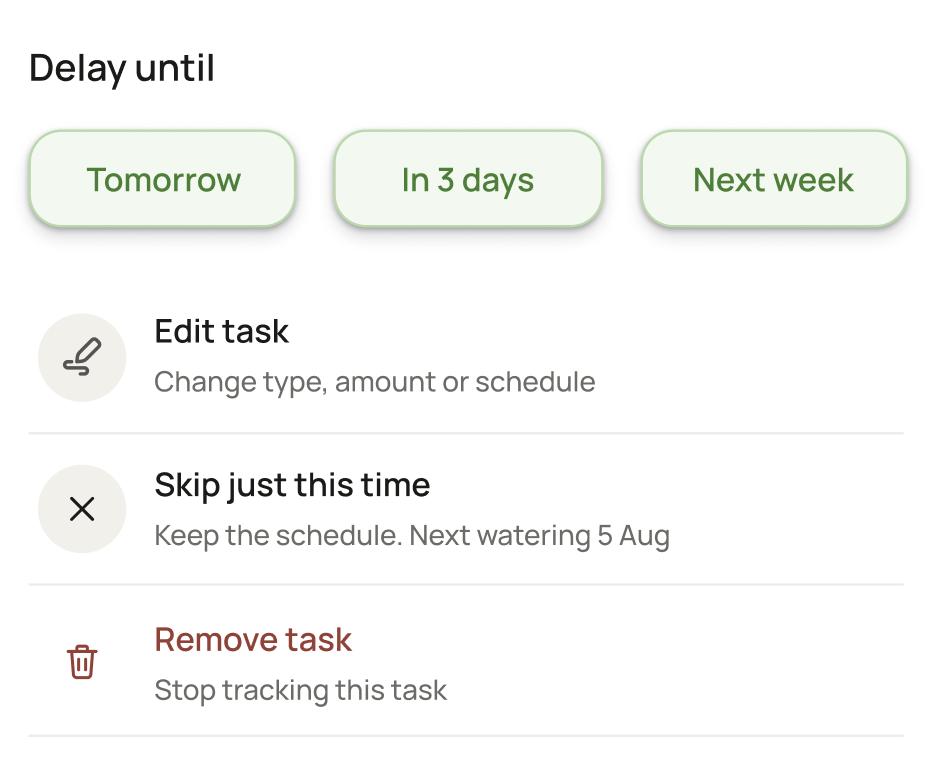
Version A went into all three surfaces. It carries an amount, so nothing in the app says “water well” again. That was the change people asked for most, and it was made in the component rather than as a new feature.
Tasks before faces
I deleted my two favourite screens. A stories row and a sign-up flow. Both were finished, both looked good, both answered the wrong question first.
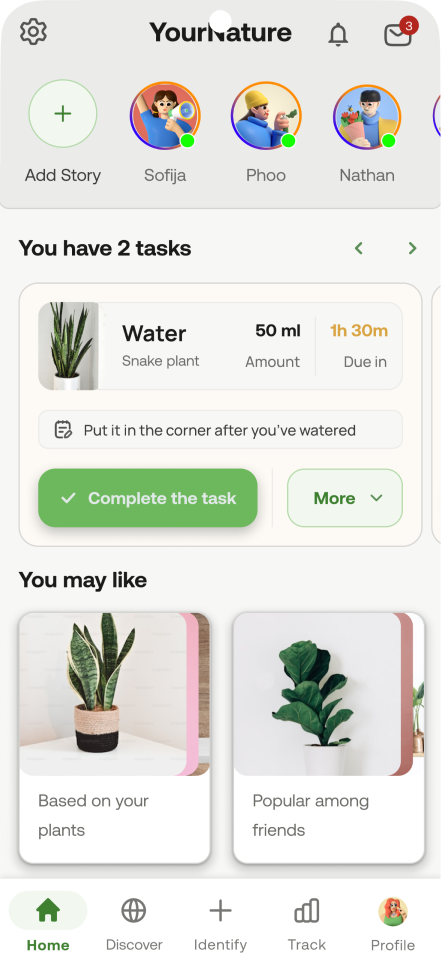
People said the hobby felt lonely, so I gave the top of home to friends' stories and put a sign-up form in front of everything. The app looked alive the second you opened it. But it gave the most valuable strip of the app to other people, so your own plants ended up below the fold. And in my interviews people described opening a plant app when something had already gone wrong, which is a bad moment to ask for an email.
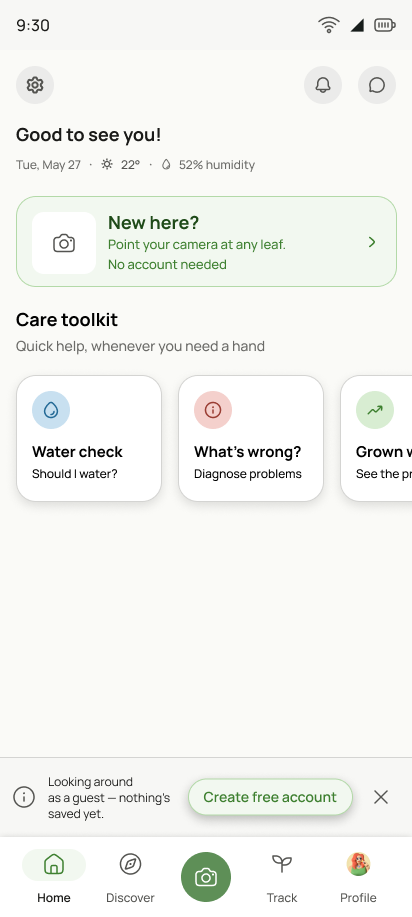
Guest onboarding, running
The same argument end to end. A guest gets a care plan in two questions, and only then is offered somewhere to save it. Every accommodation can be tried before it is accepted — a real reminder, a live colour setting, the silent screen flash — and “Maybe later” is a full-width option, not fine print.
It plays through once — press Restart to watch again, or jump between the five steps with the dots.
What social looks like once it stops being a feed
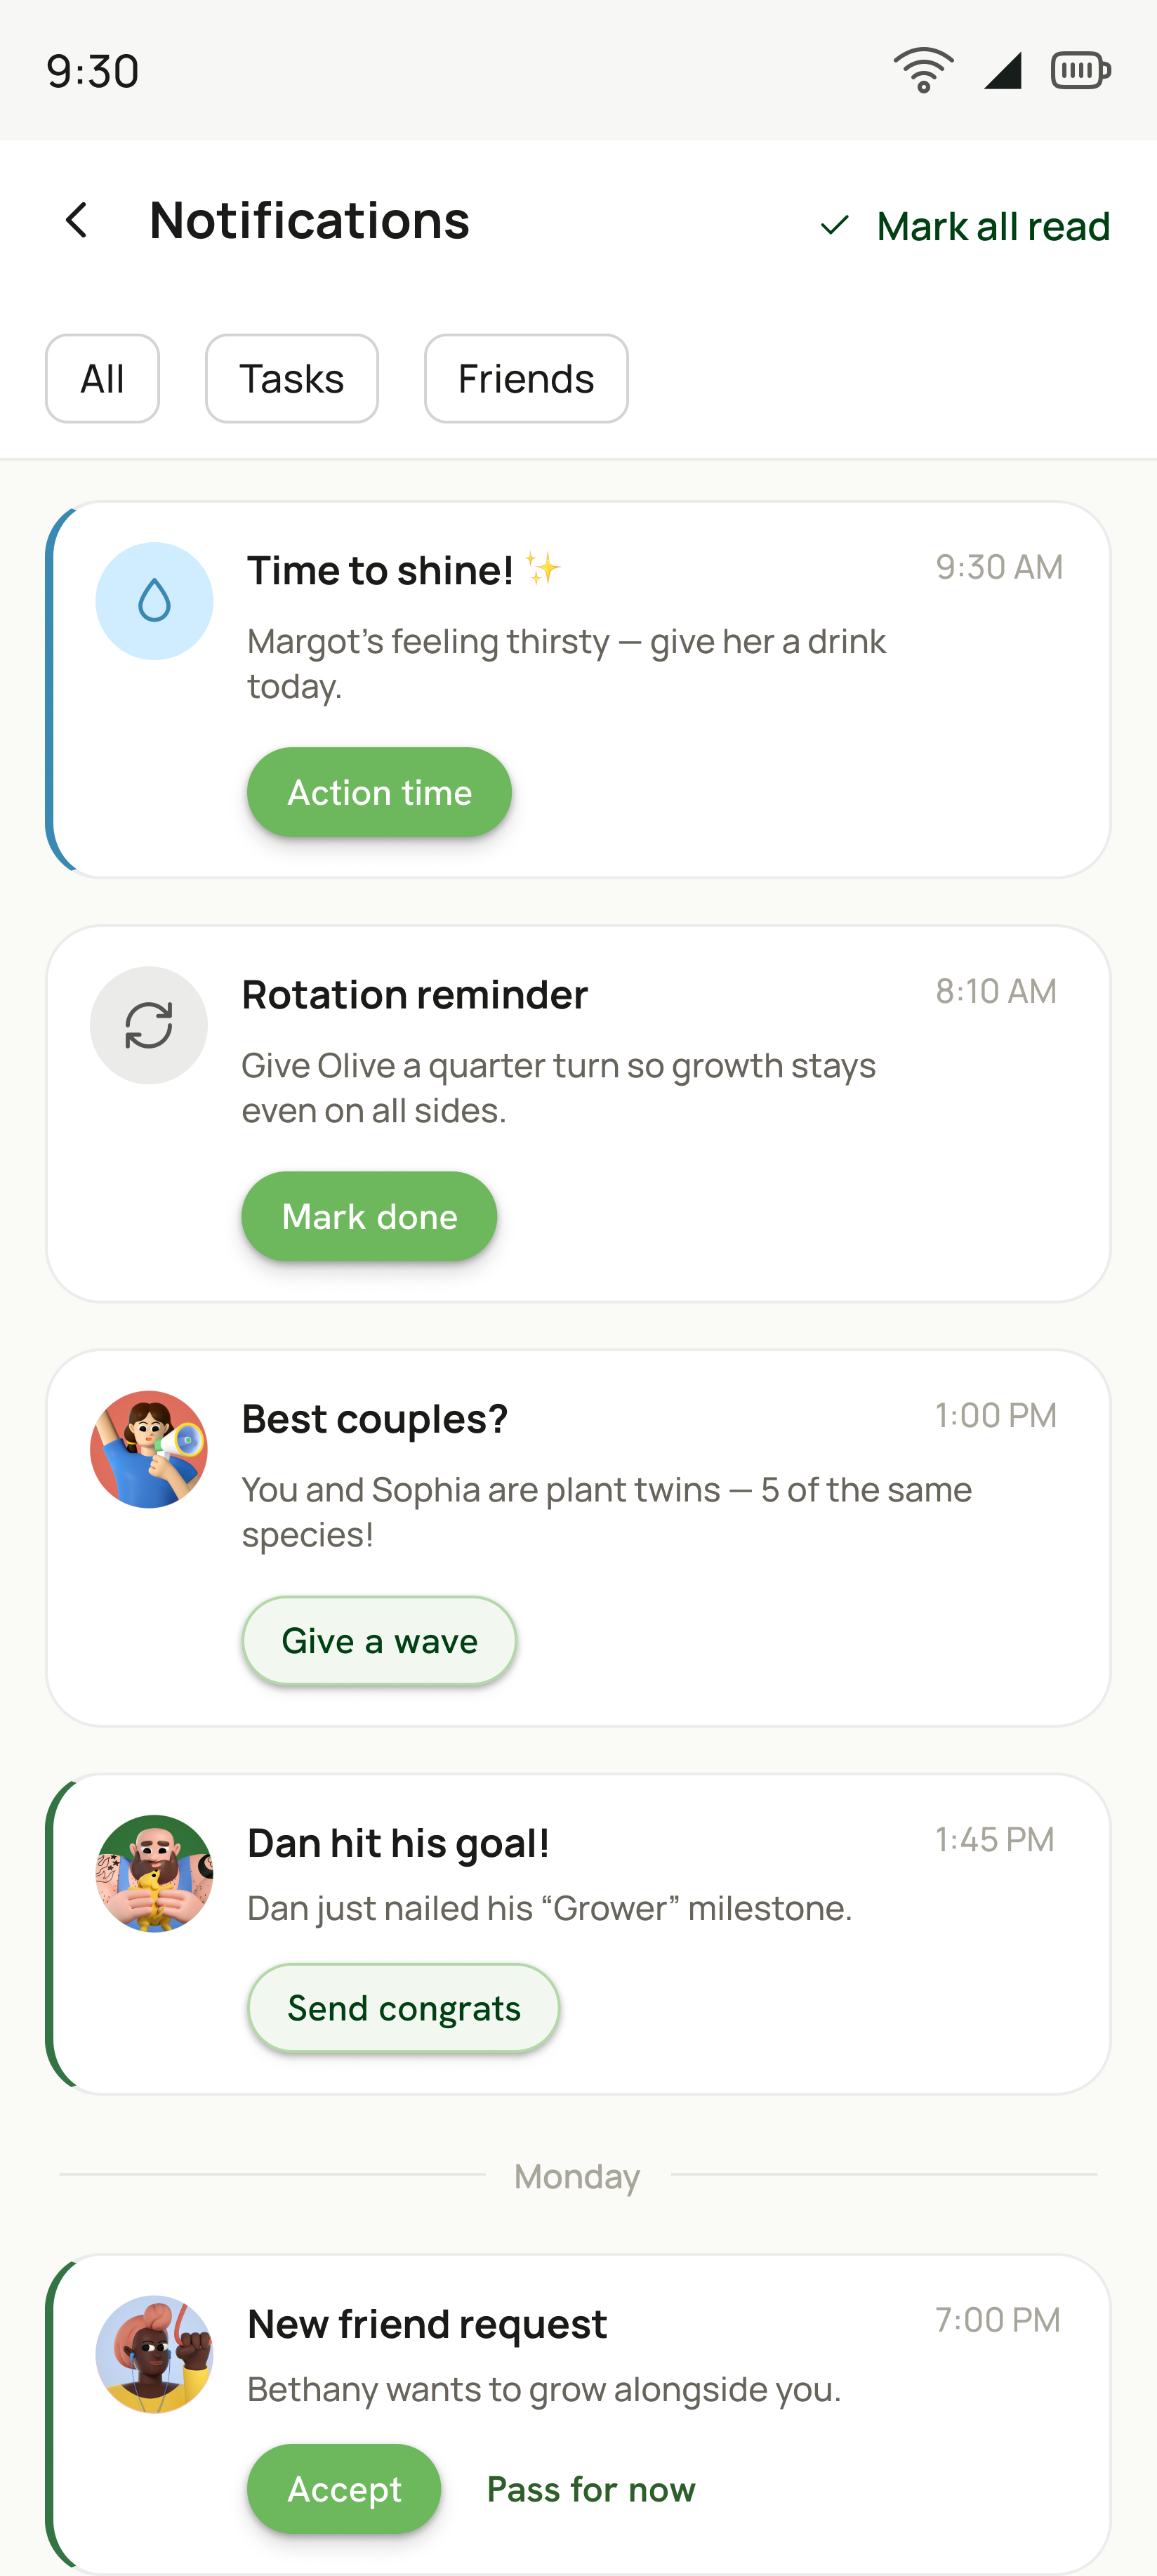
Deleting the stories row didn't delete the social part. It moved it to the moment someone actually wants it. Asking begins on the plant page of whichever plant is worrying you, so the question already has a subject before you pick anyone — and the sheet ranks friends by how long they've grown that species, so “who do I ask” is answered for you.
Press Play to watch it, or tap through the four stages yourself.
The first screen now answers “what does my plant need” before “what are my friends doing”, and the app proves itself useful before it asks for anything. Nothing a guest does is thrown away — identifications, water checks and accessibility preferences all move onto the account the moment one exists.
Reward before task
Showing the payoff before the task. This is the one decision the interviews couldn't give me. People will tell you they want motivation. What actually motivates them is a different question, and they don't know the answer. So I went to the research, which also told me what to leave out.
If a reward can be taken away, it works as a punishment too. The rule underneath all of it
| Mechanic | Call | Why |
|---|---|---|
| Streaks | Kept, rebuilt | In most apps a streak goes to zero the moment you miss a day. In this one it freezes where it is and carries on when you're back. |
| Ranking | Kept, scoped | Any ranking stays inside a community goal group, it's off unless you switch it on, and it never appears on home. |
| Surprise rewards | Cut outright | The mechanic most likely to drive repeat opening — which is why I considered it. To create the surprise it has to sometimes not pay out, so you ship a reward and a punishment together. |
| “Today makes 6” | Built last | The payoff sits above the task, on screen while you're deciding whether to do it. What I can't claim is that it changes behaviour — testing it is the next thing I'd do. |
The same card in three states
Three task cards on Today, each at a different point in the count: on track, paused after a missed week, and a plant on its first watering. The prototype then runs the three actions — mark done, delay, remove — and each one confirms in words what changed, including the date it moved to.
Press Play to run the three task actions, and every control on the screen is tappable.
How I got there, and what the research actually says
I stopped interviewing after six people asked for “motivation” and none of them could say what would motivate them. So I read about reward timing: Schultz, Dayan and Montague (Science, 1997) on the dopamine response shifting from the reward to the cue that predicts it, and Sapolsky on what sustains effort when the payoff is far off. That's single-neuron primate work and a lecture, so I treated it as a hypothesis to design against. It proves nothing about plant apps.
Then every mechanic got the same question: can this be inverted into a punishment? Streaks and global leaderboards both fail it as they're normally built. Sailer et al. and the JMIR leaderboard work both discuss ranking motivating the people at the top while lower-ranked participants report failure and inadequacy, unless the comparison is kept small. That research raised a risk I didn't want to introduce, so I rebuilt both mechanics. Being late is now only information — “1 day late” in words, with nothing taken away.
Nothing in the motivation layer can be taken off you. Missing a day costs nothing, and coming back is easy.
The payoff, on the page
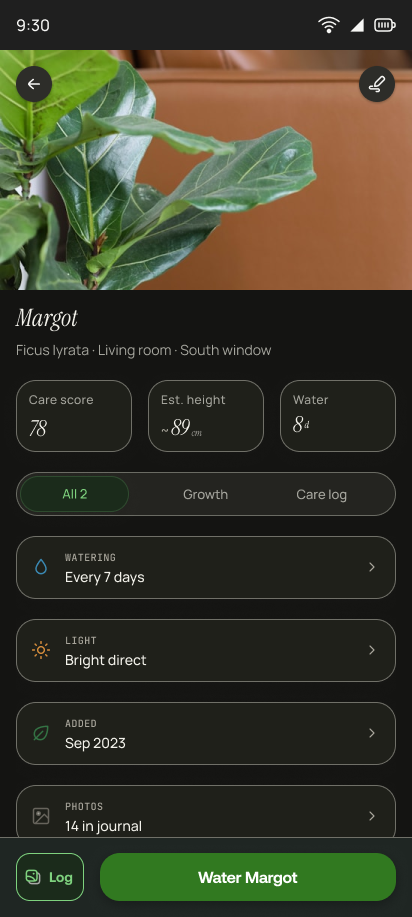
Rebuilding the plant page around what the person already did. Before, the page interpreted the plant. After, it records what the owner did. I rebuilt it four times.
The old page graded you out of 100. When someone asks why the number is 78, there is no honest answer, because the app made it up. A count is something you can check yourself and argue with. And logging a watering is admin — it takes a few seconds, nobody sees it, and the app gave nothing back for doing it. The page had to make the record itself feel worth keeping.
Scroll inside the phone to read the page from the top to the end.
What I left off the page
The obvious next feature is telling people whether the spot they chose is working. I left it out. All the app has is a phrase the person typed when they added the plant, like “living room, south window”. It has no light reading, no idea how far the pot is from the glass, whether a building blocks the sun, or whether the curtain is shut. Judging the spot from those few words would be the care score all over again — a confident answer with nothing behind it.
So the page says what the plant needs and stops there. The person standing in the room is the one who can see whether their window matches it.
Every figure on the page is something the person typed in themselves, shown back to them. Nothing is scored, estimated or averaged. That rule removed the care score, the estimated height and the verdict on the window.
The mistake
A tester broke my goal system without trying to.
The short version: a tester typed 400 trees into a goal of 500 and nothing stopped her. I tried to make claims trustworthy three different ways, and every one of them needed strangers doing unpaid work. So I stopped trying to verify claims and counted saplings instead — one crate of 250 per session, the lead writes down who took what, and a tree only counts if the crate can account for it.
An honest majority would carry it
A partner-run programme: a city body sets a goal of 10,000 trees across named sites, and the app tracks what the community puts in. I assumed a few bad numbers would be lost in the noise of hundreds of good ones.
One person could finish the goal alone
I watched someone log a contribution in the working prototype, and nothing stopped her typing 400 towards a goal of 500. I only found it by watching someone else use it, because I would never have typed 400 myself.
Count the saplings, not the claims
Saplings are physical things that arrive in a crate with a delivery slip. That is a number with a receipt attached, so that is the number the app counts. You never type your own allocation — you scan the code on the lead's crate.
250 saplings out — one crate, one session, one delivery slip from the nursery. The lead hands them out and writes down who took what.
174 went in the ground · 74 came back unplanted · 2 too damaged to plant. 250 out = 174 + 74 + 2. It adds up, or the day does not close.
A session can never count more trees than it was given saplings, so the worst a dishonest planter can do is hold back a sapling that the crate will then report as missing.
The goal page as a first-timer meets it — three numbers, not fifteen.
The three rounds of patching, in full — each fix opened a new way to game it
| What I tried | How it worked | What still went wrong |
|---|---|---|
| Round 1. A limit, a photo and two witnesses | Nobody could claim more than a set number at once. Every claim needed a photo, and two other members had to tick it off. | People plant alone, at the weekend. Real claims sat unconfirmed for days — and a fake claim sat there the same few days and then went through anyway. |
| Round 2. Stop making people wait | Ordinary claims count straight away. Only unusually large ones get flagged, and even those go through after 72 hours. | Members who confirmed others earned a higher limit. Then I realised two friends could confirm each other back and forth and raise both their limits without planting anything. |
| Round 3. Keep friends from confirming each other | Claims from anyone you follow never reach you. Earning a higher limit takes confirmations from several different members. | It worked, and I still didn't like it. All three rounds had the same shape: I was asking strangers to judge each other's photos for free. |
The idea I tried first: location as proof. Require the phone's location on every log, and only count it if it falls inside the named planting site. I dropped it for four reasons. It proves the wrong thing — a coordinate says a phone was there, not that a tree went in the ground. It makes life hard for honest people, who log on the way home with a dead battery. It asks for precise-location permission at the exact moment the feature depends on a yes. And the privacy cost lasts longer than the goal.
Then my fix caused its own problem
All that accounting had to live somewhere, and I put it on the goal page. A first-timer now met about fifteen numbers and six words I had invented — counted, pending, allocated, returned, closed, reconciled — before they could do anything. It read like an audit handed to someone who had just walked in.
So I split the page by what the person is actually doing. Haven't joined: what it is, who runs it, the next session, one button. Reserved: where to go, who to find, and a way to cancel. At the plot: the sapling card on its own. Done: what you logged and when it counts. The ring, the ledger and the nursery slips moved to one page called How the count works. Nothing was deleted, and a newcomer now sees three numbers instead of fifteen.
I stopped writing like an accountant too. Sapling ledger became Where every sapling went. Handed back to stock became came back unplanted. The crate reconciles became it adds up.
Press Play to watch it, or jump between the steps with the dots.
This came out of a usability session, not a review. Someone was using the prototype and logged trees they hadn't planted, because nothing stopped them. Everything after that grew out of that one moment: I took each fix back into a session and let the next person try to break it, three times over. A static screen can't be abused, so this never would have surfaced from looking at the file.
What is honestly unfinished: all of this now rests on the session lead's screen — handing saplings out, taking them back, finishing the count. That is the piece I would build next, and where I would want real leads testing it.
A feature I killed
Estimated height, and why it never shipped. It survived three rounds of the plant page before I cut it, and it died for the same reason the care score did: the app was telling the user something it couldn't actually know.
It started as one figure in the stat row, then it got a five-month chart, then a whole Growth tab to hold the chart, plus a recommended article teaching people how to measure properly. That last step should have been the warning. If a feature needs an article before it works, the user is doing the work for it.
It goes down when you do the right thing
Propagate a cutting, prune for shape, cut away leaves after a bad month, and the plant gets shorter while it's getting healthier. The one figure meant to reward the user ends up arguing with them.
Getting it right is expensive, being wrong more so
A model that survives pruning and propagation is a long machine-learning problem. And if the whole argument of a page is “these are your own logs, untouched”, it can't carry one guessed number in the same row.
Two charts competing for one job
A water chart and a height chart on one page both claim to be the evidence, and only one can lead. Water wins, because the user typed every bar in it.
The photo journal took its place
It shows growth without measuring it, and leaves the judgement to the person who owns the plant. If height comes back, it comes back as a measurement the user types, dated like any other log entry.
Two features died on this project for the same reason: the care score and estimated height. Both were the app telling the user something it couldn't actually know. So now I check every number the same way. If I can't answer “how do you know that”, it doesn't go on the screen.
Craft decisions
Four smaller calls worth a paragraph each.
One green was doing four jobs
Buttons, the selected tab, chart bars and icons all shared a colour, and “add fertiliser” sat right next to “toxic to your cat”. Now there are six colours with one job each, and one hard rule: a safety warning can never look like a care tip. That rule is why late tasks are described in words, and why feeding is brown and not yellow.
Why the options open in a sheet
The overflow options carry a second line of explanation, and snoozing is three chips, so there's more going on than a list of commands. A sheet also lands in the same place every time. The overflow button got the same scrutiny: a 24 dp icon in a 48 dp target, labelled “More options for Margot” — five buttons all announcing “More” is useless to a screen reader.
Set up in the first minute
Step 2 of 2, optional, and every answer changes how the app behaves: earlier and wordier reminders, status that never relies on colour alone, alerts that vibrate. The screen answers “why we ask” before anyone has to wonder.
One typeface, four spacing steps
The Figma library is built on 4 / 8 / 16 / 20 and six type sizes, which is what lets the same card sit correctly on Home, Track and Collection. Type is Manrope throughout. It isn't airtight — screens I drew before the library existed still carry values off the scale, and auditing them back on is on the list.
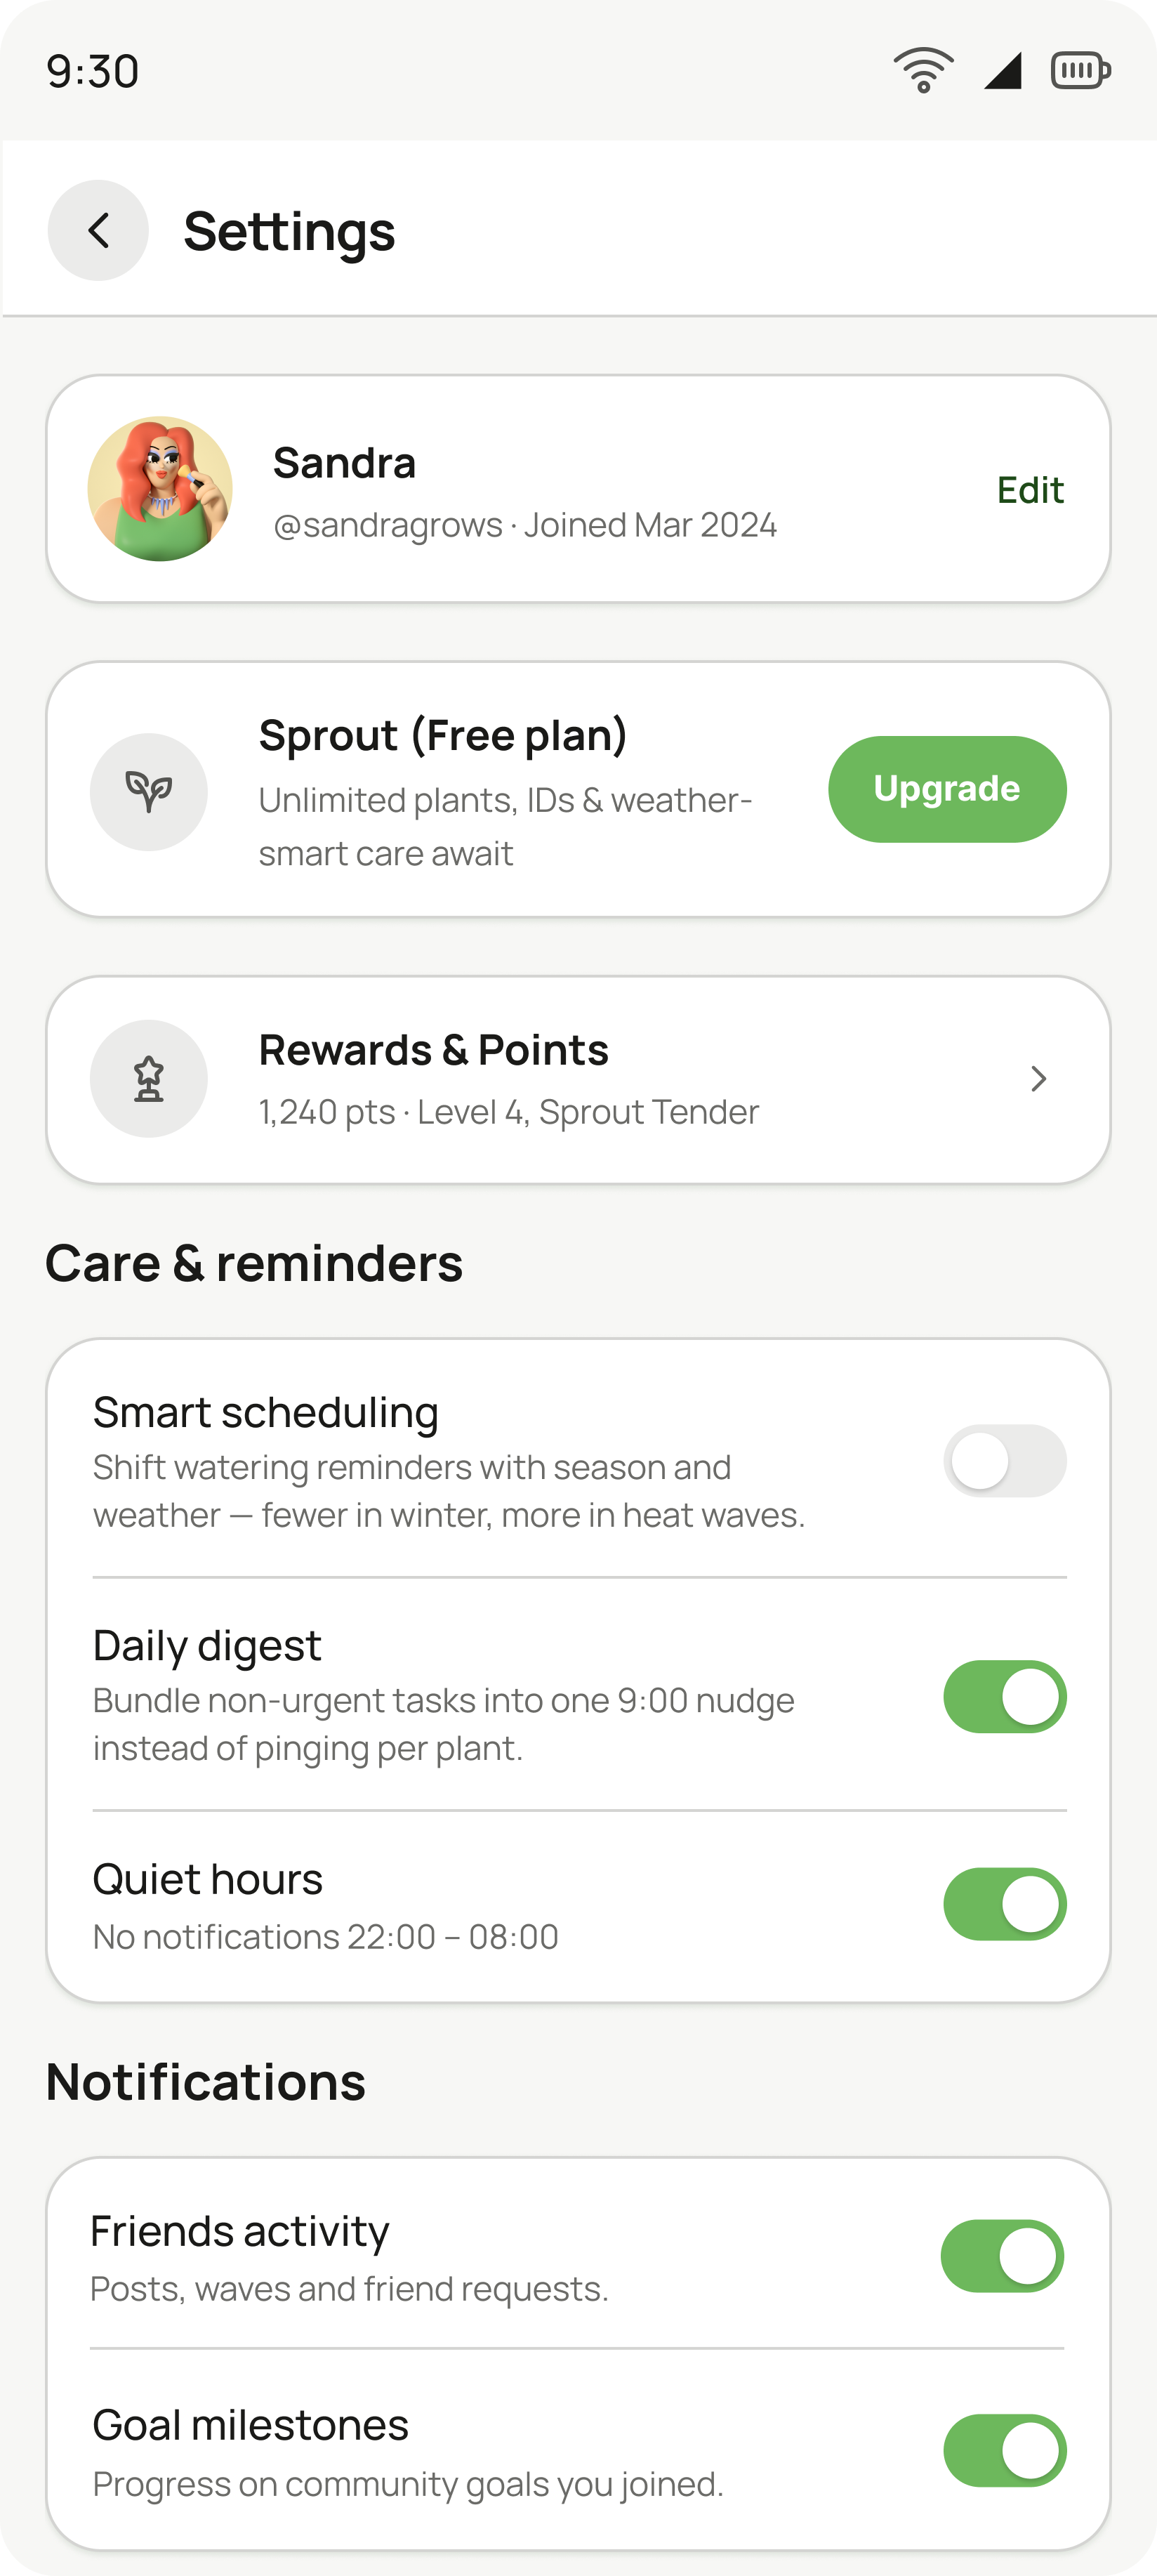
Safety information can no longer be mistaken for a care tip anywhere in the app, every menu action states its consequence before you pick it, and accessibility preferences are set in the first minute by the people who need them. Small calls, but each removes a way the app could quietly mislead someone.
How I'd validate it
A concept has no retention curve, and inventing one would be the least honest thing I could put here. These are validation plans rather than results: the tests I'd run on day one with a real team, and what each one would have to show before I trusted the design.
| Signal | How I'd test it | What would change my mind |
|---|---|---|
| Return rate after a missed day | Two weeks with the same owners, one day skipped on purpose. | If they still say the app “told them off”, the calm late state isn't calm enough. |
| Saying how much to water, unaided | One task, no help: open the app and tell me how much water this plant needs. | Any pause means the amount still isn't the first thing they see. |
| Guests turning into account holders | Guest mode against an account-first build, measured when someone tries to save a plant. | If guests look around but never sign up, the ask is in the wrong place. |
| Confidence, before and after two weeks the one that matters | One question before and after: how sure are you that you're caring for this plant correctly? | If this doesn't move, the other numbers don't matter. This is the goal the whole project was built for. |
What I'm taking to the next project
I start from the question
“Water check” came straight out of something a real person said to me. Every screen here can name its question. The ones that couldn't are deleted.
One reused component beats three good ones
Three cards were fine on their own and felt like three different apps together. One card in three places means the hierarchy I fought for holds everywhere.
I prototype to find what I can't see in Figma
The abusable goal, the empty room, the guest getting stuck. None of those were visible on the canvas. I now build prototypes hoping to be proven wrong.
Showcase
Creating a task, start to finish. The six-step flow, running.
Press Play to watch it, or jump between the steps with the dots.